Custom AI applications
Bring language, classification, and prediction capabilities into an interface built for the people using it. Connect model output to a real workflow with clear review and fallback paths.
 Get started
We build intelligent systems, AI agents, and machine learning solutions. We also deploy and optimize the infrastructure they need to run.
A useful AI system begins with a specific task: finding an answer in internal documents, classifying incoming requests, or helping a team complete a routine workflow. We define the task, the quality threshold, and the boundaries before selecting a model. The application, its knowledge sources, and the infrastructure are designed together.
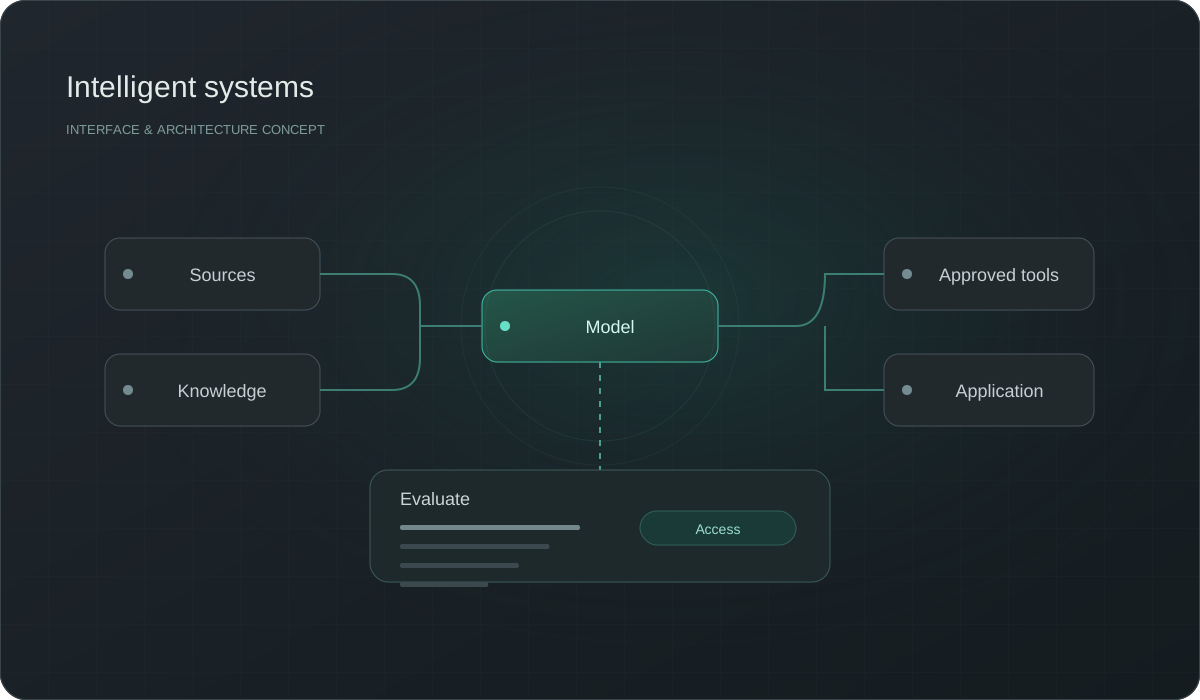
Bring language, classification, and prediction capabilities into an interface built for the people using it. Connect model output to a real workflow with clear review and fallback paths.
RAG connects a model to selected documents through ingestion, indexing, and retrieval. Permissions, source references, and document freshness are part of the knowledge system.
Give an agent access to defined tools and business APIs. Set approval boundaries, record actions, and provide recovery steps for workflows that can affect business records.
Compare existing models against representative examples, language needs, latency, cost, and privacy requirements. Evaluate the whole application rather than relying on a model leaderboard.
Training a new model, fine-tuning existing weights, and deploying an existing model are different projects. We assess data quality, licensing, compute capacity, and the expected benefit before choosing one.
Size memory and compute for the chosen workload. Quantization, batching, and serving choices are evaluated against output quality; arbitrary hardware cannot run every model.
Documents need more than an upload button. We plan extraction, chunking, metadata, access filtering, and updates, then test whether retrieved passages actually support the answer. Users should be able to inspect a source and recognize when an answer needs human verification.
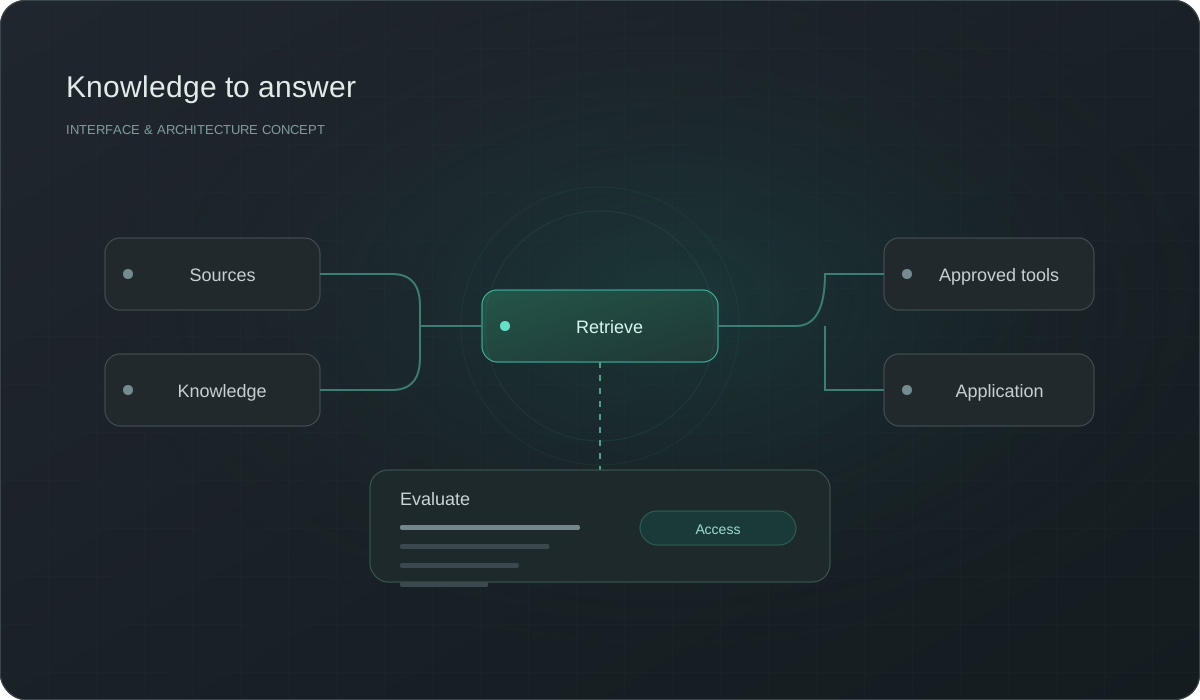
Local and offline deployment can support controlled data handling, while online services offer different operational tradeoffs. We assess connectivity, available accelerators, model licenses, maintenance responsibility, and integration needs. The final architecture can combine local components and approved cloud services.
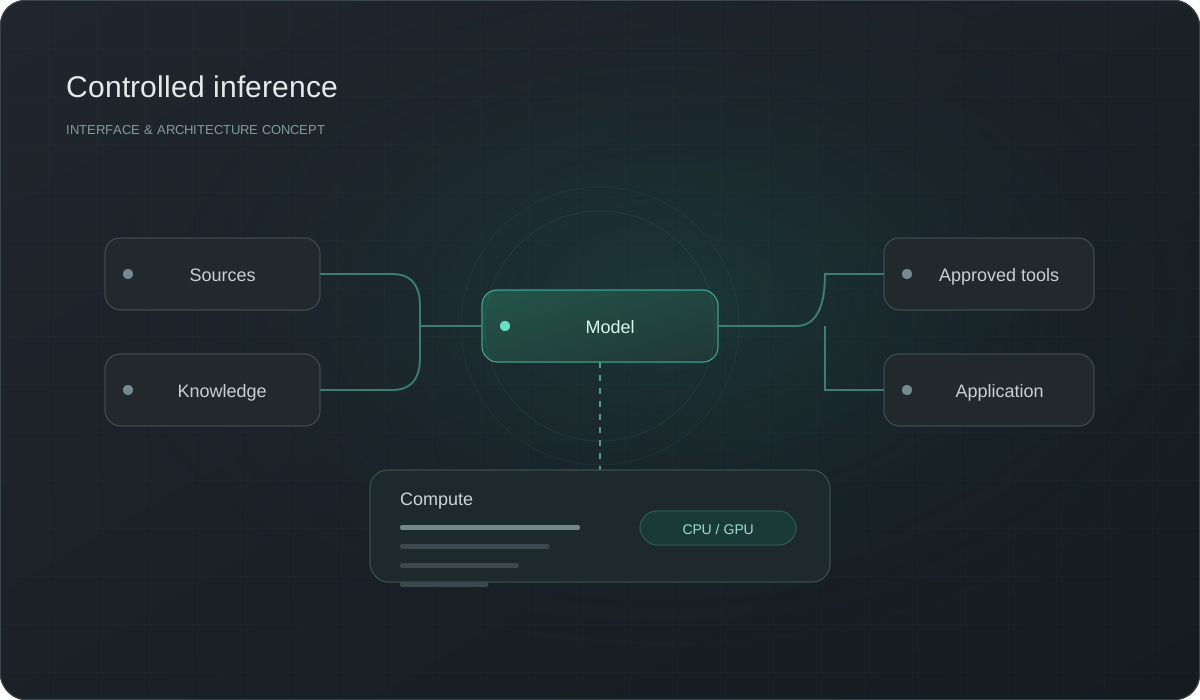
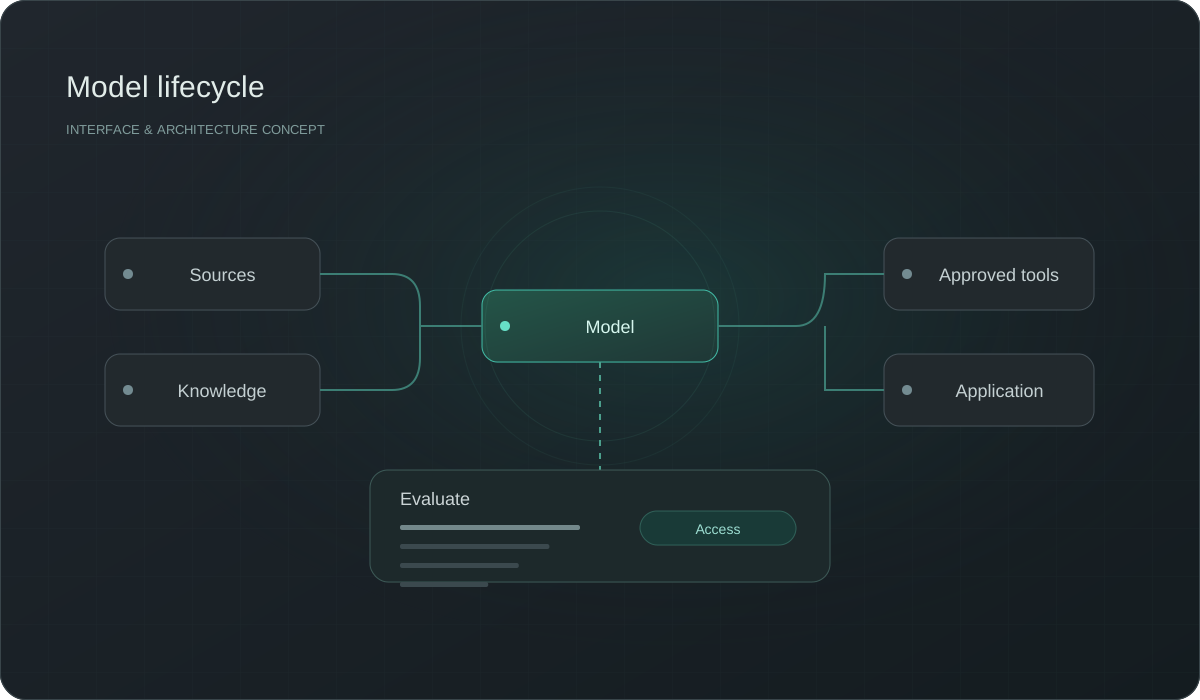
Each release needs evidence that the system helps with the intended task.
Collect representative inputs and agree on useful, unacceptable, and uncertain outputs with the people who know the work.
Prototype retrieval, prompts, tools, and any adaptation. Compare quality, resource use, and failure modes before wider integration.
Track evaluation results, model versions, and operational issues. Update knowledge and dependencies through a controlled release process.
Bring relevant organizational information closer to the person making a decision.
Keep human review and ownership explicit for consequential actions.
Plan model serving, knowledge updates, and support alongside the interface.
Often an existing model with good retrieval and integration is the sensible starting point. Fine-tuning or new training needs a clear quality gap, suitable data, and sufficient compute.
A local design may be possible when the model license, hardware, data sources, and tools allow it. We verify these requirements rather than assuming every online capability has an offline equivalent.
We define approved storage and processing locations, permissions, retention, and logging. Retrieval must respect the same access boundaries as the original information.
We assess available APIs and data interfaces, then define narrowly scoped tools. Actions that change business records can include a human approval step and an audit trail.
Have an idea, a question, or a challenge to solve? Tell us what you need, and we'll help you find the right starting point.
Tell us what you have in mind. You can reach our team directly by email.
We'll take time to understand your needs, discuss the possibilities, and work out what makes sense for your project.
Tell us about your idea, your challenge, or your next project. We’ll help you find the right way forward.